首页 > 资讯 > SGLang-TorchTPU:TPU上的PyTorch原生生产级服务

SGLang-TorchTPU:TPU上的PyTorch原生生产级服务

赢政天下 2026-10-21 08:09 4 阅读 查看原文
SGLang-TorchTPU:TPU上的PyTorch原生生产级服务

SGLang-TorchTPU今日正式开源,由RadixArk的SGLang团队与Google、Meta合作打造。
SGLang-TorchTPU

发布模型包括Muse Spark Open、GLM-5.3 Flash、GLM-5.3、Kimi K3、DeepSeek V4、Ling 3.1 Flash、Qwen3.8、Gemma 4和MiniMax H3。该插件将完整SGLang功能集引入TPU,已在Meta大规模生产环境验证,适合代理式工作负载。

工作原理

SGLang-TorchTPU是树外插件,通过sglang-tpu包注册TPU平台。SGLang核心调度器、RadixAttention和API服务器保持不变,插件提供注意力后端、KV缓存池、MoE内核和图运行器。
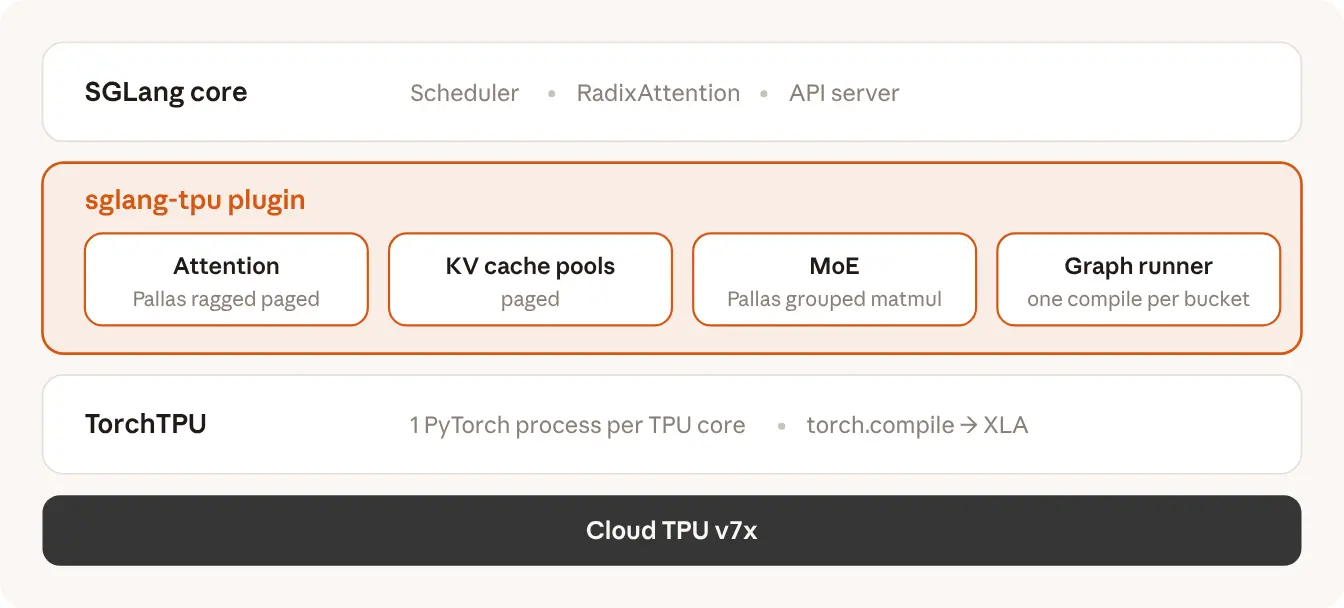
SGLang core (scheduler, RadixAttention, API server) on top of the sglang-tpu plugin (Pallas ragged paged attention, paged KV cache pools, Pallas grouped matmul MoE, a graph runner that compiles once per bucket), on TorchTPU (one PyTorch process per TPU core, torch.compile to XLA), on Cloud TPU v7x.

每个TPU核心运行独立PyTorch进程,模型通过torch.compile降至XLA。注意力与MoE使用Pallas内核实现。

KV缓存传输

通过TPU Sync实现KV缓存卸载与预填充-解码分离,支持跨主机重分片。
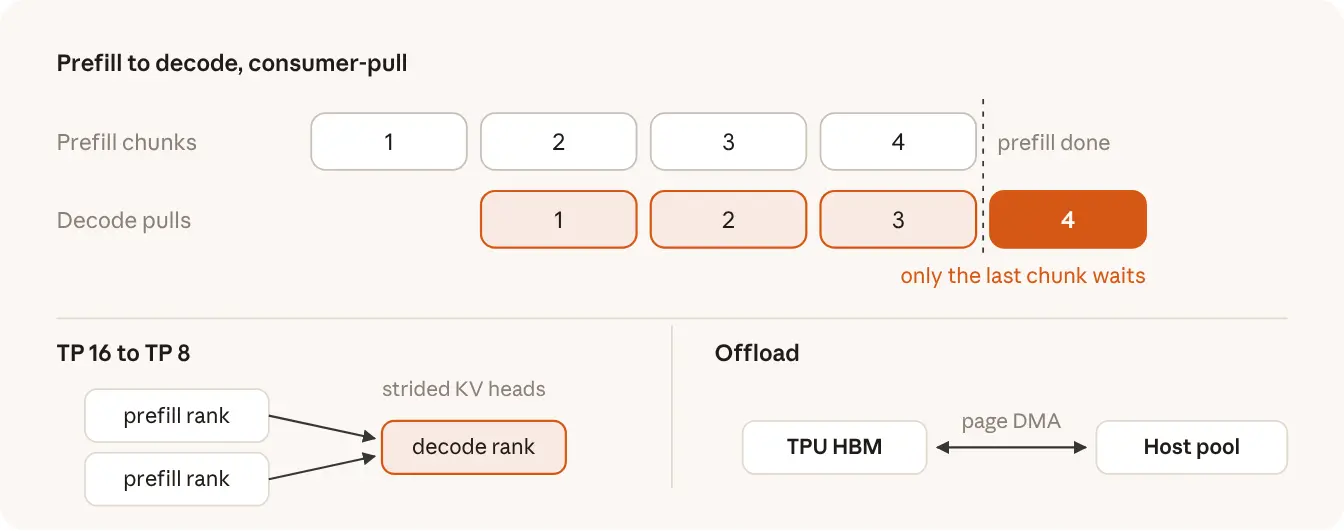
KV cache transfer with TPU Sync: decode pulls each prefill chunk while the next computes, so only the last chunk waits; TP 16 to TP 8 reshards strided KV heads; offload moves KV pages between TPU HBM and a host pool by DMA.

功能与模型覆盖

支持OpenAI兼容API、连续批处理、RadixAttention前缀缓存、推测解码、上下文并行、多模态及跨主机张量并行等特性。已支持Qwen3-VL等视觉语言模型。

可靠性保障

所有支持模型与功能均通过TPU v7x真实硬件CI测试。
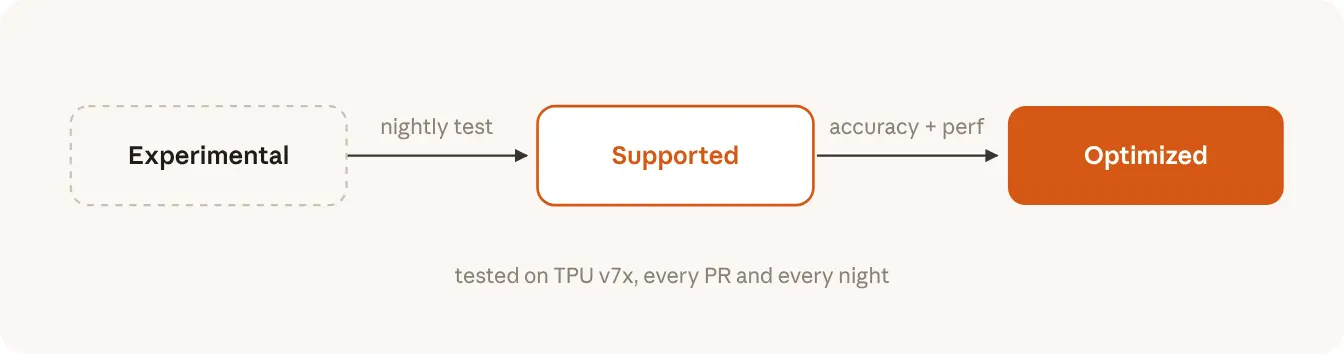
SGLang-TorchTPU support tiers: Experimental moves to Supported with a nightly test, and Supported moves to Optimized with accuracy and performance tests, all on TPU v7x every PR and every night.

TPU上的RL训练

结合TorchTitan与Miles框架实现端到端强化学习。
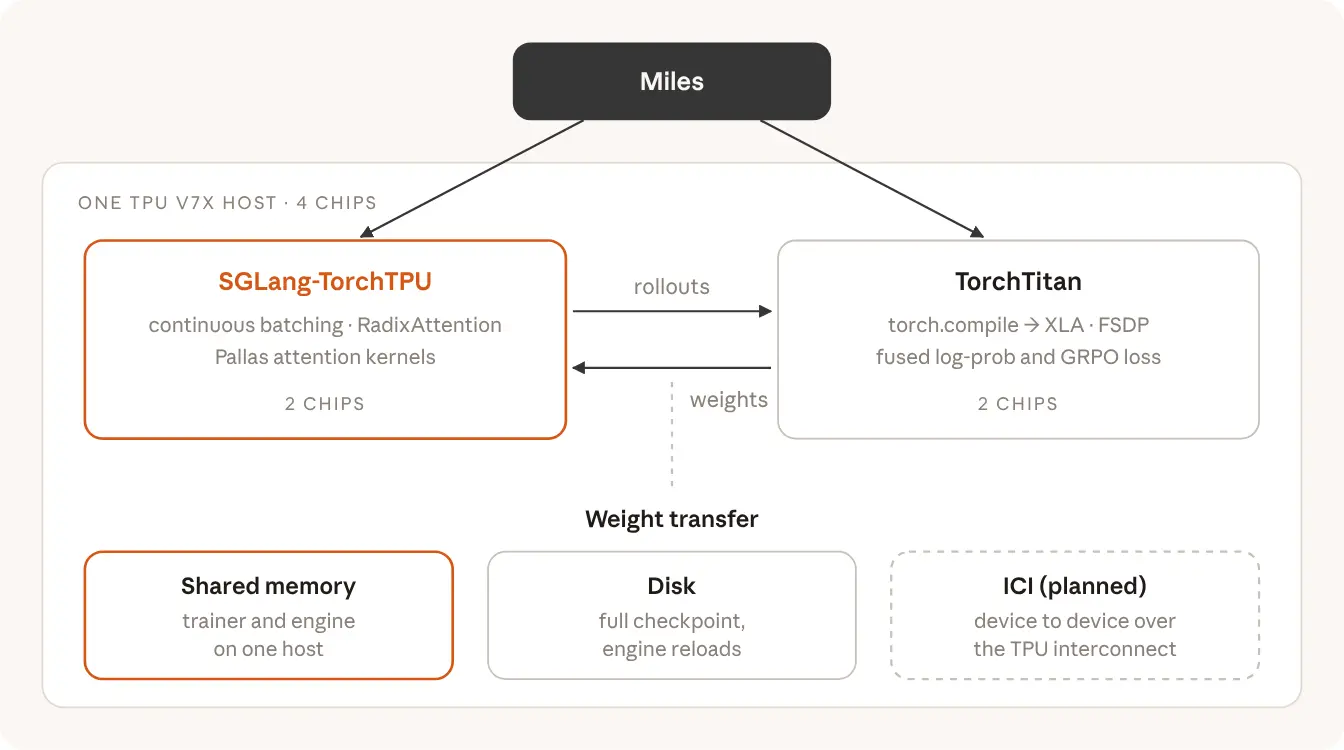
RL training with Miles on one TPU v7x host: SGLang-TorchTPU generates rollouts on 2 chips, TorchTitan trains on 2 chips, and new weights move back to the engine through shared memory, disk or ICI (planned).

Qwen3-4B GRPO实验显示,4颗TPU v7x芯片性能与6张H200 GPU相当。
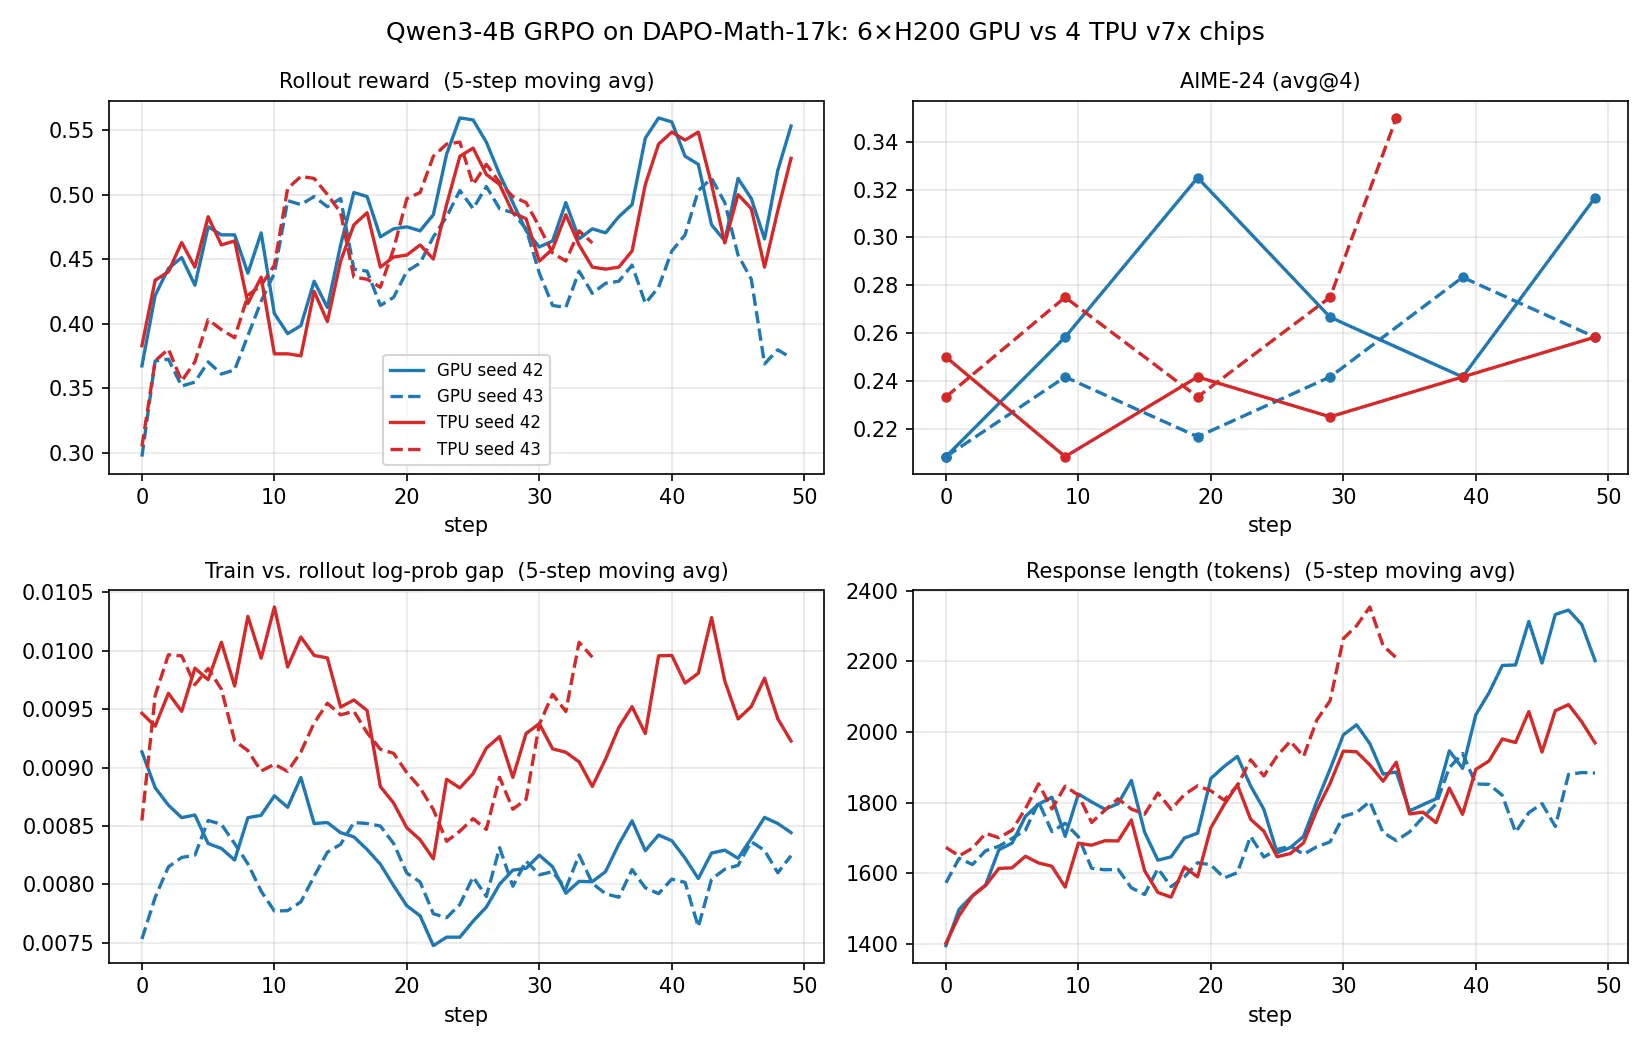
Qwen3-4B GRPO on DAPO-Math-17k: 6x H200 GPU vs. 4 TPU v7x chips